Why 95% of AI Pilots Fail and What Building Across Two Continents Taught Us Shares Imran Tariq & Jun Xiong
Earlier this year, MIT’s NANDA initiative published a number that stopped me mid-scroll: 95% of generative AI pilots at companies are failing.
.
Opinions expressed by Entrepreneur contributors are their own.
You're reading Entrepreneur Asia Pacific, an international franchise of Entrepreneur Media.
What if the AI model was never the thing holding your company back?
Earlier this year, MIT’s NANDA initiative published a number that stopped me mid-scroll: 95% of generative AI pilots at companies are failing. Not struggling. Failing. About 5% are seeing any real return at all. The researchers interviewed 150 leaders, surveyed 350 employees, and analyzed 300 public AI deployments to get there.
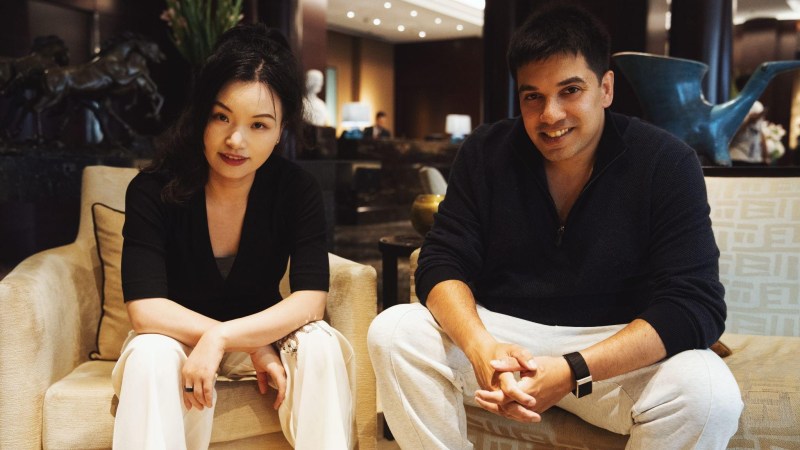
I recognized the shape of that failure immediately, because my co-founder Jun Xiong and I had already spent a year building around it half of that year working across two very different AI markets at once shares Imran Tariq.
We didn’t get there by picking a better model. We got there by fixing what we were asking the model to do.
The model was never the problem
The MIT team’s lead author, Aditya Challapally, named the pattern behind the number: “Almost everywhere we went, enterprises were trying to build their own tool.” Homegrown AI succeeded roughly a third of the time. Tools built with outside expertise, adapted to how a company actually worked, succeeded about twice as often. The other consistent failure mode was generic tools that couldn’t learn from or adapt to a company’s actual workflows they answered questions well and improved nothing.
We almost made the same argument to Forbes months earlier, before I’d seen MIT’s data: “LLMs memorize, but agentic AI learns.” Those are not the same skill, and most companies never get past the first one. Seeing that instinct confirmed by 300 real deployments was a strange kind of validation the good kind, and the uncomfortable kind, because it meant the mistake was as common as I’d suspected.
The Asia lesson nobody talks about
Here’s the part of this I don’t see written about enough: the “build it yourself” mistake looks different depending on which AI ecosystem you’re building in.
Jun spent years running a bilingual property and lettings operation in London that managed more than 1,000 clients, developing business into Beijing and Hong Kong along the way. That put her inside two very different assumptions about how AI tools are supposed to work the Western model ecosystem and the Chinese one long before either of us used the term “second brain.”
Most Western companies that we talk to default to whichever US model is loudest that month. Most of the founders I’ve met building out of Asia do the opposite, and default to whichever local model has the best support in their language. Both groups make the same mistake: they pick a model first and force their workflow to fit it, instead of building the structure their company actually needs and then choosing whichever model Western or Asian does that specific job best. We do the second one, deliberately, because Jun’s background gives us no reason to default to either camp and is how we co-founded Prime Movers AI together.
Build the memory before you build the tool
Once we accepted that the model wasn’t the problem, the real work started: giving the AI a company to actually operate inside of.
Feed a model every file a company owns and you don’t get something smarter. You get something slower, sorting through a pile it was never built to hold. What worked instead was structuring it the way a company structures its own departments — each part holding exactly what one job needs, nothing more.
The piece of that we lean on hardest is what we call an SOP librarian: a standing function whose only job is to become the memory of the company. Every SOP, every checklist, every meeting note and decision, every policy, every client onboarding step, every question that keeps getting asked twice. Solve a problem once, and it’s captured. Improve a process, and the old version gets replaced instead of left behind to confuse the next person who finds it. Most shared drives are where documentation goes to be forgotten. We built ours to stay current, and to cite its source instead of guessing — the same integration gap MIT’s data flagged as one of the biggest reasons pilots stall.
Find the one thing actually holding you back
The second piece runs across models instead of inside just one, pulling on whichever tool fits Claude, Codex, or otherwise to find the single constraint actually limiting a company’s throughput. Not the twelve minor fixes that feel productive and change nothing. The one that does. It runs on its own schedule, the same way a morning briefing does, so nobody has to remember to ask for it.
The takeaway
MIT put a number on a mistake I’d already watched play out inside my own company before I fixed it: 95% of AI pilots failing, mostly for reasons that have nothing to do with the model itself. If you’re building an AI system right now, the question worth asking isn’t which model is best. It’s whether you’ve built your company a memory before you handed it a tool — and whether you’re choosing that tool based on your workflow, or just on whichever market you happen to be standing in.
What if the AI model was never the thing holding your company back?
Earlier this year, MIT’s NANDA initiative published a number that stopped me mid-scroll: 95% of generative AI pilots at companies are failing. Not struggling. Failing. About 5% are seeing any real return at all. The researchers interviewed 150 leaders, surveyed 350 employees, and analyzed 300 public AI deployments to get there.
I recognized the shape of that failure immediately, because my co-founder Jun Xiong and I had already spent a year building around it half of that year working across two very different AI markets at once shares Imran Tariq.
Writes on advanced manufacturing, automation, and the commercial impact of deep technology.